Course project · Optimization for Machine Learning · Saarland University
AdaGrad and Adam with gradient differences
What changes when AdaGrad and Adam adapt their step sizes from successive gradient differences rather than gradient magnitudes?
- Source code (opens in a new tab)
- Project report (opens in a new tab)
- Project poster (opens in a new tab)
- Python
- PyTorch
- scikit-learn
- ResNet-34
- VGG-19
Watching the gradient change
Modern optimizers such as AdaGrad and Adam do not use a single learning rate for the whole model. They give every parameter its own step size and adjust it as training goes: a parameter whose gradients keep coming out large is given smaller, more cautious steps, while a rarely-active one keeps larger steps. The signal driving that adjustment is the size of the recent gradients.
This project asks a simple what-if. What if the step adapts instead to how much the gradient changes from one update to the next? A gradient that swings around from step to step hints that the loss surface is bending sharply there (exactly where smaller steps are safer), while a gradient that barely moves suggests a gentle slope where larger steps are fine. Swapping the size of the gradient for its change is a one-line edit to each optimizer; the question is whether that edit actually helps.
To find out, the same change is tried on four problems of increasing difficulty: a two-dimensional bowl where every step can be drawn, logistic regression on three real datasets, an image classifier trained on CIFAR-10, and neural style transfer, where the pixels of an image are themselves what gets optimized. The short answer is that there is no free lunch. The modified optimizers help on some problems, fall behind on others, and tie on several, and that mixed picture is the real result: changing one signal inside an adaptive optimizer does not make it uniformly better.
The modification
AdaGrad keeps a running total of each parameter’s squared gradients and divides the step by the square root of that total. A parameter that has seen large gradients builds up a large total, and therefore takes small steps:[01]01Duchi, Hazan, and Singer (2011), “Adaptive Subgradient Methods for Online Learning and Stochastic Optimization,” JMLR.
\[ G_{t,i}=G_{t-1,i}+g_{t,i}^{2}, \qquad \theta_{t+1,i}=\theta_{t,i} -\eta\frac{g_{t,i}}{\sqrt{G_{t,i}}+\epsilon}. \]The change proposed here swaps one quantity in that running total. Instead of the gradient $g_t$ itself, it accumulates the difference between the current gradient and the previous one,
\[ \Delta g_t=g_t-g_{t-1}, \]and uses the total of those squared differences as the denominator:
\[ \widetilde G_{t,i}=\widetilde G_{t-1,i}+(\Delta g_{t,i})^{2}, \qquad \theta_{t+1,i}=\theta_{t,i} -\eta\frac{g_{t,i}}{\sqrt{\widetilde G_{t,i}}+\epsilon}. \]Only the denominator changes; the step still points along the current gradient. Adam gets the same treatment: its running average of the gradient (which sets the direction) is left alone, and only the part that scales the step is fed squared gradient differences in place of squared gradients:
\[ \begin{aligned} m_t &= \beta_1m_{t-1}+(1-\beta_1)g_t,\\ \widetilde v_t &= \beta_2\widetilde v_{t-1} +(1-\beta_2)(\Delta g_t)^2. \end{aligned} \]Why might this carry useful information? The difference between two consecutive gradients is a rough read on curvature: how quickly the slope of the loss is bending as the parameters move. Where the gradient shifts a lot between steps, the surface is curving sharply and smaller steps are safer; where it barely shifts, the surface is nearly flat and larger steps are fine. That is the kind of second-order signal a full curvature calculation would provide, obtained here for free from gradients the optimizer already computes.
The catch is that this is not clean curvature. The change in the gradient also depends on how big the last step was and which way it went, so it blends curvature with the route the optimizer happens to be taking, and, in mini-batch training, with the random noise of sampling. So there is good reason to expect it to help on some problems and not on others, which is exactly what the experiments below show.
A visible two-dimensional trace
The first test is deliberately tiny, so every step can be drawn. The objective is a simple bowl with a single lowest point at the origin:
\[ f(x,y)=2x^2+3y^2-2xy-1. \]Its contour lines are nested ellipses around that minimum. Each optimizer starts from the same off-centre point and takes fifty steps at a fixed learning rate; the control switches between the AdaGrad pair and the Adam pair.
Loading interactive chart…
On this easy bowl the standard and modified optimizers behave similarly overall (both curve inward and settle near the minimum), but the swapped denominator visibly changes the route each one takes. The trajectories bend and settle differently even though the objective, the starting point, and the learning rate are identical. That is the whole point of the plot: it shows the modification genuinely changing how the optimizer moves, on a problem simple enough to watch, before the later experiments ask whether that change actually helps on real, noisy, high-dimensional tasks.
Logistic regression under feature translation
The next experiment leaves the drawable world for three real datasets: Pima Diabetes (768 examples, 8 features), Credit Card Fraud (284,807 examples, 29 features), and Ionosphere (351 examples, 34 features). Each is split 80/20 into training and validation data, three times over with different random splits. Before training, every feature is standardized, shifted and rescaled so its values sit in a common range, using statistics computed only on the training data, and the same transform is then applied to the validation data so no validation information leaks in.
Two versions of the features are then compared: the standardized ones, and the same features with 100 added to every value. Shifting everything by a constant should make no difference to what a linear classifier can learn (the best decision boundary is identical), so this is a clean way to test something subtler: whether the optimizer’s own behaviour is thrown off by data that is technically equivalent but badly centred.
AdaGrad uses learning rate $10^{-2}$ and Adam uses $10^{-3}$. Diabetes and Ionosphere run for 100 epochs; Credit Card Fraud runs for 20. Because the fraud dataset is highly imbalanced, the comparison records ROC-AUC, average precision, and balanced accuracy rather than relying on raw accuracy. It also records the final binary cross-entropy validation loss.
ROC-AUC, average precision, and balanced accuracy are scores, so higher is better. Validation loss measures prediction error, so lower is better. The arrows in the panel headings make this direction explicit.
Loading interactive chart…
Two patterns stand out, and the panels above hold the exact numbers. On the normally standardized features, the gradient-difference variants give a small but consistent edge on Diabetes and Ionosphere, and leave the imbalanced fraud dataset essentially unchanged. The +100 shift is the bigger story: even though it should not matter, accuracy collapses for all four optimizers on two of the datasets, and the gradient-difference variants do not rescue it. So the modification can nudge results in the model’s favour when the data is well-centred, but it does nothing about the deeper sensitivity to a badly-centred starting point.
As with the two-dimensional bowl, these are trends from a handful of runs rather than a statistically firm ranking.
CIFAR-10 with and without batch normalization
The medium-scale experiment trains a ResNet-34 on CIFAR-10.[02]02Krizhevsky (2009), “Learning Multiple Layers of Features from Tiny Images.” [03]03He et al. (2016), “Deep Residual Learning for Image Recognition,” CVPR 2016. The ImageNet stem is replaced by a $3\times3$, stride-1 convolution and no max pooling, which preserves more spatial detail in $32\times32$ images. Training uses random crops and horizontal flips; validation uses only tensor conversion and CIFAR normalization.
Each optimizer trains for 100 epochs at learning rate $10^{-3}$ and batch size 256. A second version replaces every batch-normalization layer with an identity mapping. Batch normalization changes both network parameterization and optimization geometry, so this is a substantial model condition rather than an isolated optimizer setting.[04]04Ioffe and Szegedy (2015), “Batch Normalization: Accelerating Deep Network Training by Reducing Internal Covariate Shift,” ICML 2015.
Loading interactive chart…
| Optimizer | Best accuracy without BN | Best accuracy with BN |
|---|---|---|
| AdaGrad | 68.42% | 81.82% |
| AdaGrad + difference | 63.91% | 79.61% |
| Adam | 85.60% | 92.89% |
| Adam + difference | 79.80% | 92.86% |
No gradient-difference variant exceeds its standard counterpart here. With batch normalization, Adam and Adam-with-difference are effectively tied at their best epochs (92.89% and 92.86%). Without batch normalization the gap is larger, with standard Adam ahead by nearly six percentage points, and standard AdaGrad also leads its modified version in both conditions. Batch normalization matters far more to the final accuracy than the choice between the standard and modified optimizer.
Neural style transfer as pixel optimization
The final task is different in kind: there is no model to train. A frozen, pretrained VGG network is used only to measure an image, and the optimizer adjusts the $512\times512$ pixels of the image itself so that it keeps the content of one photograph while taking on the style of another.[05]05Gatys, Ecker, and Bethge (2016), “Image Style Transfer Using Convolutional Neural Networks,” CVPR 2016. The generated image starts from the content photograph.
Two versions of the VGG network are tested, one with batch normalization and one without, each with its own loss weights and stopping threshold. Every run uses the same hardware, so the reported GPU times can be compared directly.
Loading interactive chart…
All eight runs reach their model-specific threshold before the 200,000-step cap. Results depend on both optimizer family and feature model:
| Feature model | Optimizer | Steps to threshold | GPU time |
|---|---|---|---|
| VGG-19 | AdaGrad | 7,178 | 6.4 min |
| VGG-19 | AdaGrad + difference | 9,031 | 7.8 min |
| VGG-19 | Adam | 1,840 | 1.6 min |
| VGG-19 | Adam + difference | 1,348 | 1.1 min |
| VGG-19-BN | AdaGrad | 152,510 | 143.8 min |
| VGG-19-BN | AdaGrad + difference | 91,363 | 85.1 min |
| VGG-19-BN | Adam | 8,065 | 7.5 min |
| VGG-19-BN | Adam + difference | 5,340 | 5.0 min |
For VGG-19, the AdaGrad modification takes 25.8% more steps, while the Adam modification takes 26.7% fewer. Under VGG-19-BN, both modified methods reach the threshold sooner: 40.1% fewer steps for AdaGrad and 33.8% fewer for Adam. Runtime follows the step counts because all runs use the same hardware and image size.
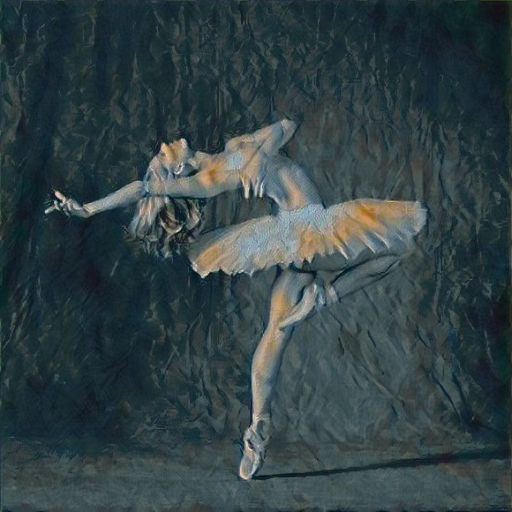
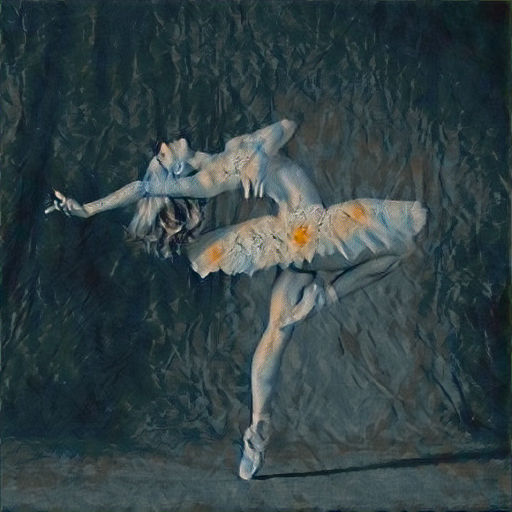
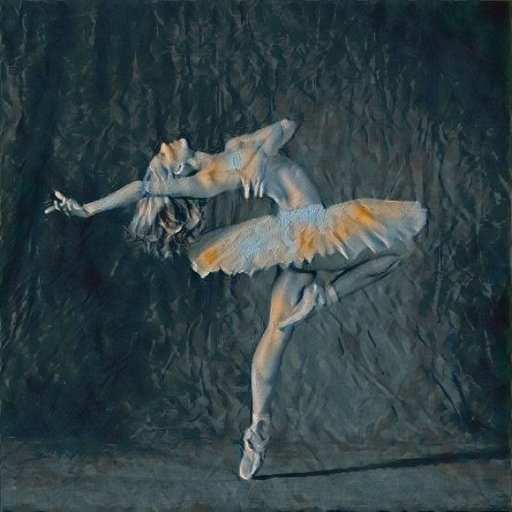
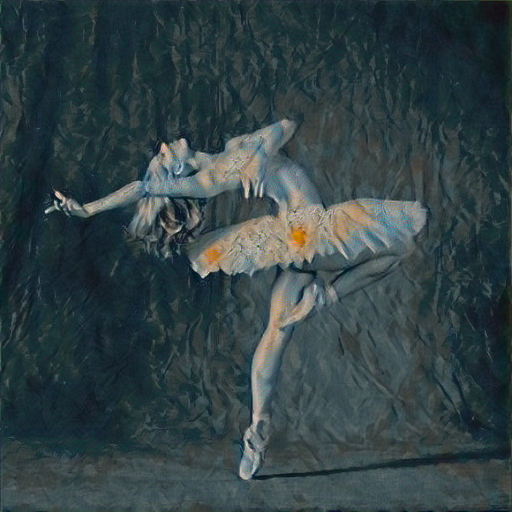
The four images below are the finished VGG-19-BN results. They look very similar because every run starts from the same photograph and stops at the same target value, so they confirm the optimization landed where it should, but they are not meant to judge which optimizer produced the nicer picture.
| AdaGrad | AdaGrad + gradient difference |
|---|---|
 |  |
| Adam | Adam + gradient difference |
 |  |
Limitations
The logistic experiment is repeated across three runs, while CIFAR-10 and style transfer use one each, so small differences should be read as trends rather than firm results. Settings were held fixed to keep the paired comparisons clean, not tuned separately for every optimizer; this favours comparability over each method’s best possible result.
Adding 100 after standardization changes both training and validation coordinates. It measures optimization sensitivity to translation, not robustness to an unseen deployment shift. CIFAR-10 reports validation accuracy from the test split used as validation, with no separate final test set. The style-transfer stopping thresholds and loss weights differ between VGG-19 and VGG-19-BN, so step counts are comparable within a feature model, not across the two models. One content-style pair and a scalar objective cannot measure perceptual quality.
The change in the gradient between two mini-batch steps mixes curvature with parameter movement, sampling noise, and data order. These experiments record what the change does, but they cannot separate which of those factors drives each result.
Conclusion
Feeding an adaptive optimizer the change in the gradient instead of its size adjusts how big each step is, without changing the direction the step points. Across the four problems, that swap never wins outright: it gives a small edge on two of the logistic datasets, does little once the features are badly centred, trails the standard optimizers on CIFAR-10, and reaches the style-transfer target in fewer steps in three of the four cases.
The consistent theme is that the effect is conditional. Whether the change helps depends far more on the setting (batch normalization, how well the data is centred, which optimizer, what kind of problem) than on the change itself. That is the useful lesson: a small, reasonable-looking tweak to an optimizer can clearly alter how training unfolds, yet whether it counts as an improvement has to be checked task by task rather than assumed from one good result.